- Map the exact error first: Destination Host Unreachable, Request Timed Out, 0x80070035, and “default gateway is not available” each point to a different layer
- Start with
Test-NetConnection -ComputerName <hostname> -Port <port>– it tells you whether the problem is DNS, routing, or the service itself in one command - Test by hostname vs by IP to isolate DNS from routing – if hostname fails but IP succeeds, the problem is DNS
- Before resetting the network stack, back up config:
netsh -c interface dump > C:\netConfig.txt - Stack reset sequence:
netsh int ip resetthennetsh winsock resetthen reboot – in that order - Treat Winsock reset as a last resort, with extra caution on domain controllers, DNS servers, and hosts running network filter drivers
Get-NetIPConfiguration,Get-NetRoute, andGet-NetNeighborreplaceipconfig,route print, andarp -ain PowerShell workflows
Most Windows Server network troubleshooting calls have nothing to do with the network. The cable is fine. The switch is fine. DNS is answering. The problem is a corrupted Winsock stack, a stale ARP entry, a misconfigured default gateway, or a firewall rule applied silently during a policy update. Knowing which one – and in what order to check – is the difference between a 10-minute fix and a 2-hour archaeology session.
This article covers Windows Server network troubleshooting for client-side and server-side connectivity problems, organized around the errors operators actually see: Destination Host Unreachable, Ping Request Timed Out, error 0x80070035, “default gateway is not available”, no internet access, and RPC server unavailable. It uses built-in tools: Test-NetConnection, ipconfig, netsh, and the modern NetTCPIP cmdlets. AD DNS server configuration, DNS zone management, replication, and time sync are out of scope – those belong to the Active Directory DNS Problems article.
Common Windows Server Network Errors and Symptoms
| Error / Symptom | Most likely layer | First check |
|---|---|---|
| Destination Host Unreachable | Route, gateway, or ARP | route print, arp -a, gateway ping |
| Ping Request Timed Out | Host, firewall, or path | ping, tracert, Test-NetConnection |
| 0x80070035 The network path was not found | DNS, SMB, TCP 445 | Resolve-DnsName, Test-NetConnection -Port 445 |
| Default gateway is not available | IP config, route, NIC | ipconfig /all, Get-NetRoute |
| No internet access / Unidentified network | Gateway, NLA/NCSI, DNS | Gateway ping plus DNS test |
| The RPC server is unavailable | DNS, TCP 135, firewall | Name resolution plus port test |
Ping: Destination Host Unreachable
“Destination host unreachable” means a device on the path knows it can’t deliver the packet. Read the Reply from address, because it tells you which device gave up:
- Reply from the server’s own IP: the local host couldn’t reach the destination. Usually the target is on the local subnet and doesn’t answer ARP, or the subnet mask is wrong and the server thinks a remote IP is local.
- Reply from a router or gateway IP: that router has no route to the destination network, or the target subnet or VLAN is down behind it.
ping 10.20.0.15
route print
Get-NetRoute -AddressFamily IPv4 | Sort-Object RouteMetric | Format-Table
arp -a
tracert 10.20.0.15
Check the subnet mask and default gateway first, then whether a route to the destination network exists, then ARP for local targets. tracert shows the last hop that answered before the path broke. Wrong masks, missing static routes, and VLAN or upstream routing changes cover most cases here; the routing table and ARP sections below have the detail.
Ping Request Timed Out
“Request timed out” means no reply came back before the timeout. Nothing on the path said the destination was unreachable; the packet, or its reply, just disappeared. Typical causes:
- The target host is off, or its network stack isn’t answering.
- The target’s firewall drops ICMP echo. On Windows targets, echo replies need the “File and Printer Sharing (Echo Request – ICMPv4-In)” rule or an equivalent rule enabled for the active profile.
- An upstream firewall or ACL drops ICMP or the return traffic.
- A routing problem where no device sends an explicit unreachable message.
- Packet loss on the path.
A timed-out ping doesn’t prove the server is down. Test the actual service port before drawing conclusions:
ping 192.168.1.50
tracert 192.168.1.50
Test-NetConnection -ComputerName 192.168.1.50 -Port 3389
If ping times out but TcpTestSucceeded is True, the host is up and ICMP is simply filtered.
Destination Host Unreachable vs Request Timed Out
| Destination Host Unreachable | Request Timed Out | |
|---|---|---|
| What happened | A device knows it can’t reach the destination and says so | No reply arrived before the timeout |
| Who answered | The local host or a router (see Reply from) | Nobody |
| Usual layer | Routing, subnet mask, gateway, ARP | Target down, firewall filtering, or silent path loss |
| Next check | Routing table and ARP | Port test and tracert |
Error 0x80070035: The Network Path Was Not Found
Error 0x80070035, “The network path was not found”, appears when Windows can’t reach a UNC path such as \\fs01\share: in Explorer, with net use, in PowerShell, and during some domain-join operations. It’s a network-path error, so prove the path layer by layer before looking at permissions:
# 1. Does the name resolve, and to the right IP?
Resolve-DnsName fs01

# 2. Is the host reachable, and is SMB (TCP 445) open?
Test-NetConnection -ComputerName fs01 -Port 445

# 3. Does it work by IP? (separates DNS from SMB)
net use \\192.168.1.60\share

# 4. Are the SMB services running? (server side, then client side)
Get-Service LanmanServer
Get-Service LanmanWorkstation
A name that resolves to an old IP, a closed TCP 445 (the “File and Printer Sharing (SMB-In)” firewall rule or an upstream ACL), a stopped Server service on the target, or a stopped Workstation service on the client all produce the same error. If TCP 445 connects and the path still fails, the problem has moved past the network: share permissions, SMB signing, or authentication, which are outside the scope of this article.
Windows Server No Internet Access or Unidentified Network
“No internet access” on Windows Server comes from the Network Connectivity Status Indicator (NCSI), which probes Microsoft test endpoints over HTTP and DNS. A server behind a proxy, or one whose firewall blocks those probes, can show “No internet access” while internet traffic actually works. Before troubleshooting the warning, test real connectivity:
ping <default-gateway-IP>
Resolve-DnsName www.microsoft.com
Test-NetConnection -ComputerName www.microsoft.com -Port 443
Get-NetConnectionProfile
If those work, the warning is cosmetic or an NCSI probe problem. If they fail, work through the gateway, DNS, and routing layers below. “Unidentified network” means Network Location Awareness (NLA) couldn’t identify the network, usually because there’s no valid default gateway, the address is APIPA (169.254.x.x), or there is a duplicate IP. Get-NetConnectionProfile also shows the network category; a server stuck on Public instead of Domain gets the wrong firewall profile. On domain controllers, NLA can identify the network before AD DS and DNS are ready at boot, which leaves the connection on the wrong profile; restarting the Network Location Awareness service after startup is the commonly used workaround.
Why Windows Server Network Troubleshooting Goes Wrong
The most common mistake is starting at the wrong layer. An operator sees “can’t reach the server” and immediately checks firewall rules or calls the network team. Meanwhile, ipconfig /flushdns would have fixed it in 10 seconds.
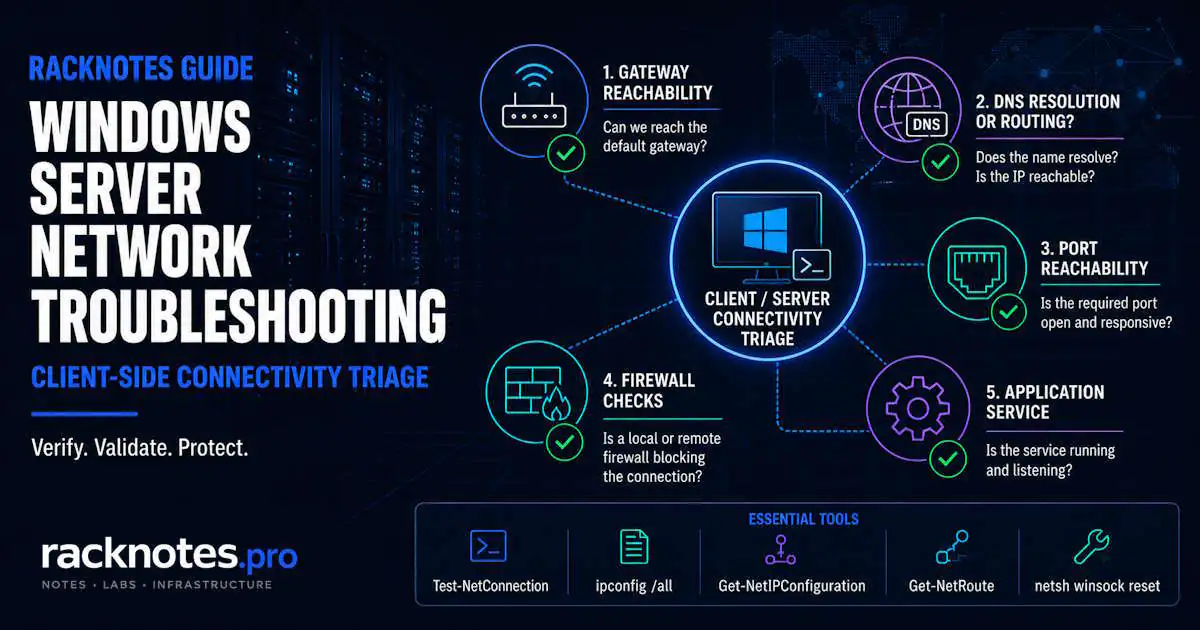
Layered triage – gateway reachability first, then DNS resolution, then port reachability, then application – eliminates that wasted time. Each layer confirms or rules out an entire category of failure before moving to the next. Skipping layers doesn’t save time – it just makes the diagnosis take longer.
The second most common mistake: resetting the network stack on an infrastructure server without planning for it. Winsock reset clears provider registrations and the IP reset can clear static settings; on a domain controller or DNS server that takes down services other machines depend on. Verify the server role before touching the stack.
Common Symptoms and Likely Causes
Before running any commands, match the symptom to the most likely cause. Windows Server network troubleshooting becomes much faster when the starting layer is already narrowed.
| Symptom | Likely Cause | Start Here |
|---|---|---|
| Hostname fails, IP succeeds | DNS – stale cache or wrong record | Resolve-DnsName, ipconfig /flushdns |
| Ping works, port connection fails | Firewall rule or service not running | Test-NetConnection -Port, netstat -ano |
| Intermittent drops, works after reboot | ARP cache stale, driver issue, DHCP conflict | arp -a, Event Viewer NetworkProfile |
| No gateway access, APIPA address shown | NIC disconnected, DHCP failure, IP misconfiguration | Get-NetAdapter, Get-NetIPConfiguration |
| Some destinations reachable, others not | Routing table – wrong metric or missing route | Get-NetRoute, route print |
| Works fine, then drops under load | Duplex mismatch, driver instability | Get-NetAdapter, NIC driver link events in the System log |
| TCP connects but application errors | Application-layer auth, NLA, TLS version mismatch | Application event log, RDP/WinRM article |
Layer 1 – Is the Gateway Reachable? (Default Gateway Is Not Available)
Confirm the server can reach its default gateway before anything else. If it can’t, the problem is local – NIC, driver, or IP config – rather than network or application. This is the fastest layer to rule out and gets skipped constantly.
ipconfig /all
ping <default-gateway-IP>
If ipconfig /all shows an APIPA address (169.254.x.x), the NIC failed to get a DHCP lease. The server either lost connectivity to the DHCP server or the NIC itself has a problem.
Get-NetIPConfiguration
Get-NetAdapter | Select-Object Name, Status, LinkSpeed
A NIC showing Status: Disconnected or LinkSpeed: 0 bps is a physical or driver issue. No stack reset will fix it. If the gateway pings fine but downstream connectivity fails, move to DNS.
When Windows reports that the default gateway is not available, check four things in order: the gateway address is in the same subnet as the server’s IP with the correct mask; there is exactly one intended default route (Get-NetRoute -DestinationPrefix 0.0.0.0/0); the NIC is up with a stable link; and, on multi-homed servers, the interface metrics send default traffic out the intended NIC. A second default gateway on an internal NIC is a frequent cause on servers with more than one adapter.
Layer 2 – DNS Resolution or Routing?
This is where most Windows Server network troubleshooting time gets lost. “Can’t reach server.contoso.com” could mean DNS isn’t resolving the name, DNS resolves it but the IP is unreachable, or the IP is reachable but the port is blocked. One command split DNS from routing:
# Test by hostname - exercises DNS + routing + port
Test-NetConnection -ComputerName server.contoso.com -Port 443

# Test by IP - bypasses DNS entirely
Test-NetConnection -ComputerName 192.168.1.50 -Port 443
Hostname test fails but IP test succeeds: DNS problem. Both fail: routing or firewall. Both succeed with TcpTestSucceeded: True: the network and TCP path work, and the remaining problem is above TCP, such as authentication, TLS, the protocol, or the application itself. That one distinction eliminates half the possible failure categories immediately.
For DNS-specific diagnosis:
Resolve-DnsName server.contoso.com
Resolve-DnsName server.contoso.com -Server 192.168.1.10   # query a specific DNS server
ipconfig /displaydns                                   # check local resolver cache
ipconfig /flushdns                                     # clear stale cache
A stale DNS cache entry pointing to an old IP is a common cause of “suddenly can’t reach X” after a server migration or IP change. When several DNS servers are configured, query each one with -Server and compare the answers. That finds the server returning a wrong or stale record. For internal names, compare internal DNS servers; an external resolver can’t answer for an internal zone. The full Resolve-DnsName parameter reference on Microsoft Learn covers filtering by record type and querying specific DNS servers.
DNS Resolution Fails or DNS Server Is Not Responding
When names fail everywhere and the client reports that the DNS server isn’t responding, check the client side before the server:
Get-DnsClientServerAddress -AddressFamily IPv4
Test-NetConnection -ComputerName 192.168.1.10 -Port 53
Resolve-DnsName server.contoso.com -Server 192.168.1.10
Confirm the configured DNS servers are the intended ones, that each is reachable on port 53 (Test-NetConnection tests TCP 53; normal queries use UDP 53 first), and that a direct query returns an answer. If the DNS server is reachable but answers wrongly, times out, or returns SERVFAIL, the problem is on the server side, covered in Windows Server DNS troubleshooting.
Layer 3 – Port Reachability and Firewall
Once the IP is reachable, confirm the specific port the application uses. This is the core of troubleshooting service-specific failures:
Test-NetConnection -ComputerName 192.168.1.50 -Port 445
Test-NetConnection -ComputerName 192.168.1.50 -Port 3389
Test-NetConnection -ComputerName 192.168.1.50 -Port 5985   # WinRM HTTP
TcpTestSucceeded: True means the port is open and a process is listening. TcpTestSucceeded: False with PingSucceeded: True means the IP is reachable but the port is blocked or the service isn’t running. At this point the problem is one of: the service isn’t running, Windows Firewall is blocking the port, or a network-level device is blocking it.
# Check firewall rules for a specific port
Get-NetFirewallRule | Where-Object { $_.Enabled -eq 'True' } |
  Get-NetFirewallPortFilter | Where-Object { $_.LocalPort -eq '445' }

# Check if the port is actually listening locally
netstat -ano | findstr :445
netstat -ano | findstr LISTENING
Check the specific inbound rule and the active profile (Get-NetConnectionProfile) before considering any broader change. Disabling Windows Firewall entirely is a short, controlled test at most, not a fix. If the host rules are correct and the port is listening, look upstream at physical firewalls or ACLs. Cross-reference the listening PID with tasklist | findstr <PID> to confirm which process owns the port.
netstat -ano | findstr :3389 shows nothing listening. TermService is stopped, or the RDP port was changed in the registry at HKLM\SYSTEM\CurrentControlSet\Control\Terminal Server\WinStations\RDP-Tcp\PortNumber. The Remote Desktop troubleshooting article covers the full listener recovery workflow.
RPC Server Is Unavailable: Check Network Connectivity First
“The RPC server is unavailable” (error 1722, 0x800706BA) often has a network cause. Before anything role-specific, confirm the basics: the name resolves to the right IP, the host is reachable, TCP 135 (the RPC endpoint mapper) is open, and the dynamic RPC port range (49152-65535 by default) isn’t blocked between the two machines.
Resolve-DnsName dc01
Test-NetConnection -ComputerName dc01 -Port 135
If TCP 135 is open but the call still fails, the dynamic ports are a common block on upstream firewalls. When the error shows up in Active Directory replication or on domain controllers, continue with Active Directory replication troubleshooting.
Routing Table – When Traffic Goes the Wrong Way
After a NIC addition, VLAN change, or static route misconfiguration, traffic can exit through the wrong interface. That causes a lot of confusion after infrastructure changes.
Get-NetRoute -AddressFamily IPv4 | Sort-Object RouteMetric | Format-Table
# or
route print
Look for multiple default routes (0.0.0.0/0) with identical or similar metrics – traffic may route through the wrong gateway. Also check for missing routes to specific subnets and stale persistent routes left from decommissioned NICs or old VLAN configs.
# Add a temporary route (survives until reboot)
route add 10.20.0.0 mask 255.255.255.0 192.168.1.1

# Add a persistent route (survives reboots, not NIC replacements)
route add -p 10.20.0.0 mask 255.255.255.0 192.168.1.1
Persistent routes don’t survive NIC replacements. Document them – they’re easy to forget and hard to diagnose six months later when “everything worked until we swapped the NIC.”
ARP Cache – The Silent Connectivity Killer
ARP cache entries go stale when a NIC is replaced, a VM is migrated, or an IP is reassigned. The server holds an IP-to-MAC mapping. If that mapping is wrong, packets go to the old MAC and disappear silently – no error, no event, just nothing.
arp -a                    # display ARP cache
Get-NetNeighbor           # PowerShell equivalent
arp -d <IP>              # delete specific entry
arp -d *                  # flush entire ARP cache
After clearing the entry, the next connection attempt triggers a new ARP request and gets the correct MAC. This fixes “worked yesterday, failing today after a network change” and takes 30 seconds. It gets skipped constantly because it sounds too simple.
Event Log – Networking Event Sources
The Windows event log has several sources relevant to Windows Server network troubleshooting. Intermittent drops and NIC instability show up here before they show up anywhere else.
| Event Source | Log Location | What It Covers |
|---|---|---|
| Tcpip | System | TCP/IP stack errors, duplicate IP detection (Event ID 4199) |
| DNS Client Events | Apps and Services Logs > Microsoft > Windows > DNS Client Events > Operational | DNS resolution attempts, failures, NXDOMAIN responses |
| NetworkProfile | Apps and Services Logs > Microsoft > Windows > NetworkProfile > Operational | Network category changes, NIC connect/disconnect (Event ID 10000, 10001) |
| Netlogon | %SystemRoot%\debug\netlogon.log | Domain connectivity and DC discovery failures – a text log, written only after Netlogon debug logging is enabled with nltest /dbflag:0x2080ffff |
# Check for duplicate IP conflicts (Event ID 4199)
Get-WinEvent -LogName System |
  Where-Object { $_.Id -eq 4199 } | Select-Object -First 10 TimeCreated, Message

# Check DNS Client Events operational log
Get-WinEvent -LogName 'Microsoft-Windows-DNS-Client/Operational' -MaxEvents 50 |
  Where-Object { $_.LevelDisplayName -in @('Error','Warning') } |
  Select-Object TimeCreated, Id, Message

# Check NIC connect/disconnect events
Get-WinEvent -LogName 'Microsoft-Windows-NetworkProfile/Operational' -MaxEvents 20 |
  Select-Object TimeCreated, Id, Message
Event ID 4199 (duplicate IP address) generates an ARP conflict and causes intermittent connectivity failures that look like random drops. It gets consistently misdiagnosed as a driver or switch problem until the event log is checked. For a deeper walkthrough of event log filtering and incident hygiene, see the Windows Server Event Log Troubleshooting article.
Network Stack Reset – When and How
Winsock corruption still happens – usually after failed VPN client uninstalls, antivirus stack components, or botched driver updates. Symptoms: TCP connections drop randomly while ping works, or netsh winsock show catalog shows unexpected LSP entries. This is a last resort, not a first move. Microsoft Learn documents the full netsh command reference including interface and Winsock context syntax.
Before resetting anything, back up the current config:
netsh -c interface dump > C:\netConfig.txt
netsh winsock show catalog > C:\winsock-before.txt- Back up current config:
netsh -c interface dump > C:\netConfig.txt - Reset IP stack:
netsh int ip reset - Reset Winsock:
netsh winsock reset - Reboot – both resets require a reboot to take effect
- After reboot, verify with
Get-NetIPConfigurationandTest-NetConnection -ComputerName 8.8.8.8 -Port 53 - If a static IP was configured manually, re-apply it – the IP reset clears static assignments
netsh winsock show catalog before resetting and check with the vendor if unfamiliar entries appear.
Packet Capture – When Connectivity Tests Aren’t Enough
Test-NetConnection and netstat confirm whether connections succeed or fail. They don’t show why a connection is being reset mid-session, what’s in the packets, or whether an upstream device is sending RSTs. When the layer tests are inconclusive, a packet capture is the next step.
Windows Server has two built-in capture tools that require no installation:
# netsh trace - full packet capture (all supported Windows Server versions)
netsh trace start capture=yes tracefile=C:\capture.etl maxsize=500

# Reproduce the problem, then stop
netsh trace stop
# Convert the .etl to .pcapng with Microsoft's etl2pcapng tool, then open it in Wireshark
# pktmon - lightweight built-in capture (syntax below: Windows Server 2022 and later)
pktmon start --capture --comp nics --pkt-size 0 -f C:\pktmon.etl
# Reproduce the problem, then stop
pktmon stop
# Convert to pcap format for Wireshark
pktmon etl2pcap C:\pktmon.etl --out C:\pktmon.pcappktmon first shipped with Windows Server 2019, but the capture and etl2pcap syntax shown above arrived in later builds; on Server 2019 and Server 2016, netsh trace is the safer choice. Neither tool requires a reboot or affects running services. What to look for in captures: TCP RST packets from an unexpected source (upstream firewall blocking mid-session), retransmissions indicating packet loss, or SYN packets that receive no response (port blocked at a network device, not at the server). Microsoft Learn documents the full pktmon reference and output format.
Modern NetTCPIP Cmdlets vs Legacy Commands
The legacy commands still work on Server 2025. The PowerShell equivalents return objects rather than text, making them better for scripting and scheduled health checks as part of any Windows Server network troubleshooting workflow.
| Task | Legacy | PowerShell |
|---|---|---|
| Show IP configuration | ipconfig /all |
Get-NetIPConfiguration |
| Show routing table | route print |
Get-NetRoute |
| Show ARP cache | arp -a |
Get-NetNeighbor |
| Show active connections | netstat -ano |
Get-NetTCPConnection |
| Show DNS cache | ipconfig /displaydns |
Get-DnsClientCache |
| Flush DNS cache | ipconfig /flushdns |
Clear-DnsClientCache |
| Test connectivity and port | telnet <host> <port> |
Test-NetConnection -Port |
| Resolve DNS name | nslookup |
Resolve-DnsName |
| Show NIC status and speed | ipconfig |
Get-NetAdapter |
What Breaks: Common Windows Server Network Troubleshooting Failures
- Confirm the port result is
TcpTestSucceeded: True– not justPingSucceeded: True - Test-NetConnection only confirms the TCP handshake – it does not validate application-layer authentication
- For RDP: check NLA requirements, Remote Desktop Users group membership, and active session count with
qwinsta - For WinRM: check TrustedHosts with
Get-Item WSMan:\localhost\Client\TrustedHosts - Check the application event log on the remote server for authentication failures
- Run
netsh winsock show catalogto see currently registered providers - A third-party LSP (VPN client, DLP agent, endpoint security tool) was registered and not reinstalled after reset
- Identify the missing provider from the pre-reset catalog backup at
C:\winsock-before.txt - Reinstall the relevant software, or contact the vendor for the LSP reinstall procedure
- If no backup exists, check the installed software list for VPN clients or security tools that inject into the network stack
- Check for duplicate IP:
Get-WinEvent -LogName System | Where-Object { $_.Id -eq 4199 } - On a working machine in the same subnet, run
arp -aand check whether the MAC for the conflicting IP matches - On multi-homed servers, check
Get-NetRoutefor metric conflicts – traffic may exit through the wrong NIC - Check NIC binding order in Network Connections advanced settings if multiple NICs serve the same subnet
- Run
Resolve-DnsName <hostname>and confirm the returned IP is the expected one - After a server migration or IP reassignment, DNS may still return the old IP
- Test the resolved IP directly with
Test-NetConnection -ComputerName <IP> -Port <port> - If the IP test also fails, the target server or its upstream path is the problem – not DNS
- If the IP test succeeds but the hostname test fails, clear the DNS cache:
Clear-DnsClientCache
Verification Workflow Before Escalating
Before calling the network team or opening a ticket, run through this sequence and document the results. The escalation will ask for this output anyway – run it first.
# 1. IP configuration and gateway
ipconfig /all

# 2. Gateway reachability
ping <default-gateway-IP>

# 3. DNS resolution - which server answered, what IP returned
Resolve-DnsName <hostname>

# 4. TCP reachability by name (DNS + routing + port)
Test-NetConnection -ComputerName <hostname> -Port <port>

# 5. TCP reachability by IP (bypasses DNS)
Test-NetConnection -ComputerName <IP> -Port <port>

# 6. Is the port listening locally?
netstat -ano | findstr :<port>

# 7. Routing table anomalies
Get-NetRoute -AddressFamily IPv4 | Sort-Object RouteMetric | Format-Table

# 8. ARP cache for relevant IPs
arp -a

# 9. Recent network-related events
Get-WinEvent -LogName System -MaxEvents 200 |
  Where-Object { $_.Id -eq 4199 -or $_.ProviderName -like '*Tcpip*' } |
  Select-Object TimeCreated, Id, Message
Scope: What This Article Does Not Cover
- AD DNS server configuration – SRV records, zone types, forwarders, conditional forwarders: see the Active Directory DNS Problems article linked in the introduction
- AD replication over site links – site link costs, replication schedules, KCC: see the Active Directory replication article linked in the RPC section above
- RDP and WinRM recovery – listener repair, port conflicts, error 0x80338012: covered in the Remote Desktop troubleshooting article linked above
- NIC teaming and SET – covered in Hyper-V Networking
- SYSVOL replication and time sync – see SYSVOL replication issues and Active Directory time synchronization
- Storage troubleshooting – disk errors, CHKDSK, SMART: see the Windows Server Storage Troubleshooting article
Final Thoughts
Effective Windows Server network troubleshooting is mostly a discipline problem, not a knowledge problem. The tools are simple and haven’t changed much. What changes the outcome is running them in the right order and not skipping layers.
The layered approach – gateway, then DNS, then port, then application – resolves most connectivity complaints without needing the network team. The cases that genuinely require upstream investigation become much easier to scope when you can hand over exact Test-NetConnection output, a routing table dump, and a packet capture showing RSTs from an upstream device rather than from the server itself.
Stack resets are the last resort, not the first move. Many connectivity problems resolve at the ARP cache or DNS cache layer. Winsock corruption is real but uncommon – and resetting it on the wrong server creates more problems than it solves.
Windows Server Operations Series
8 articles — Event Logs · Performance · Services · Remote Access · Network · Storage · Backup · Boot Recovery